KuaFu: Compressing Long User Behavior into Understanding at Billion Scale
Preprint, 2026 · arXiv:2609.31045 · cs.IR, cs.CL, cs.LG
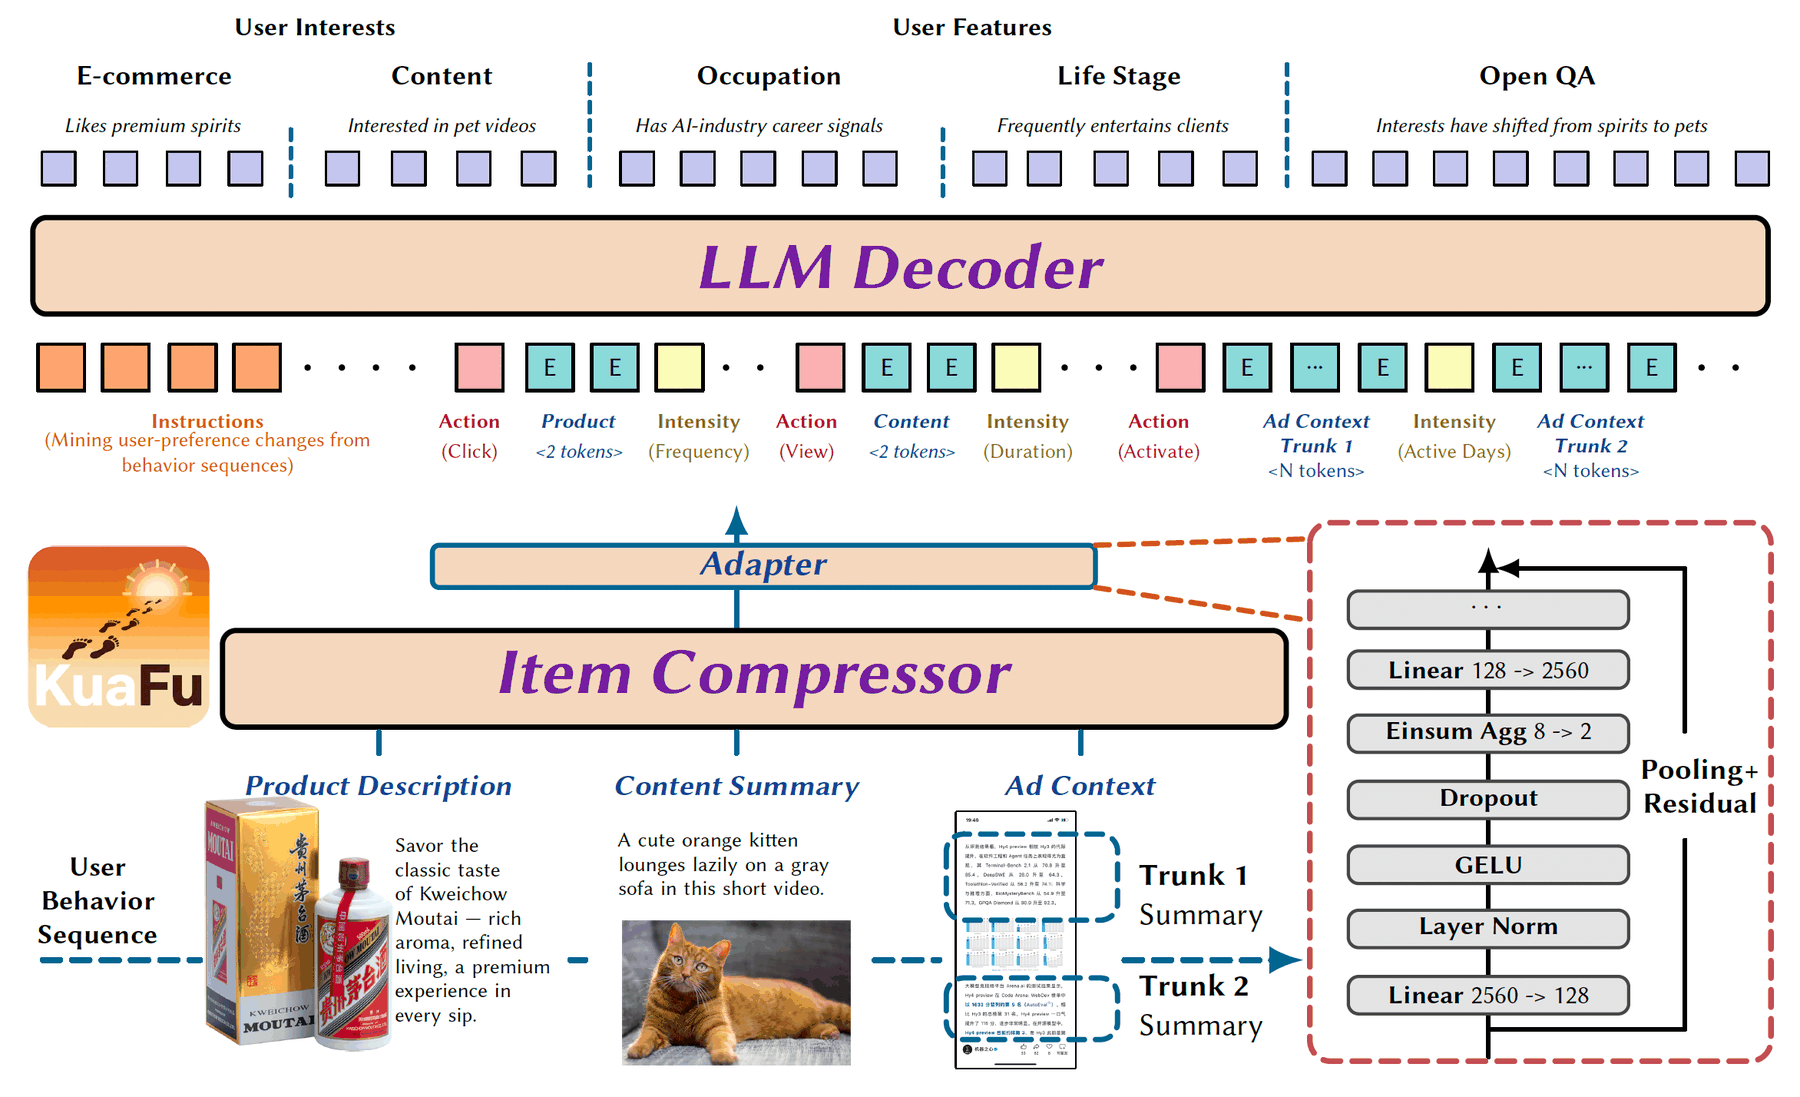
A unified behavior-compression layer whose minimal unit is one behavior item: each item is compressed into 2–4 tokens of width 128–256, matching or exceeding uncompressed single-task production models on all five headline metrics while raising per-GPU throughput by 37%–350% and saving 190 GPUs. Deployed on the Tencent advertising and recommendation platform for ten months, lifting overall GMV by 1.37%.